DeepInfra
 Apply
About
At DeepInfra, we're building high-performance AI infrastructure that makes running the world's best AI models fast, reliable, and accessible. We operate across the entire inference stack — from GPUs all the way to the API — and we care deeply about performance, efficiency, and solving hard engineering problems.
A technical challenge for the 3blue1brown audience
Puzzles are a bit of an obsession around here. Whether it's a logic grid, an algorithmic problem, or a stubborn bug in production, we can't leave a good one alone. Our colleague Johan de Ruiter takes it further: he designs puzzles as a hobby, and he made a few for you. Have fun, and let us know how you solved them!
Super Slitherlink
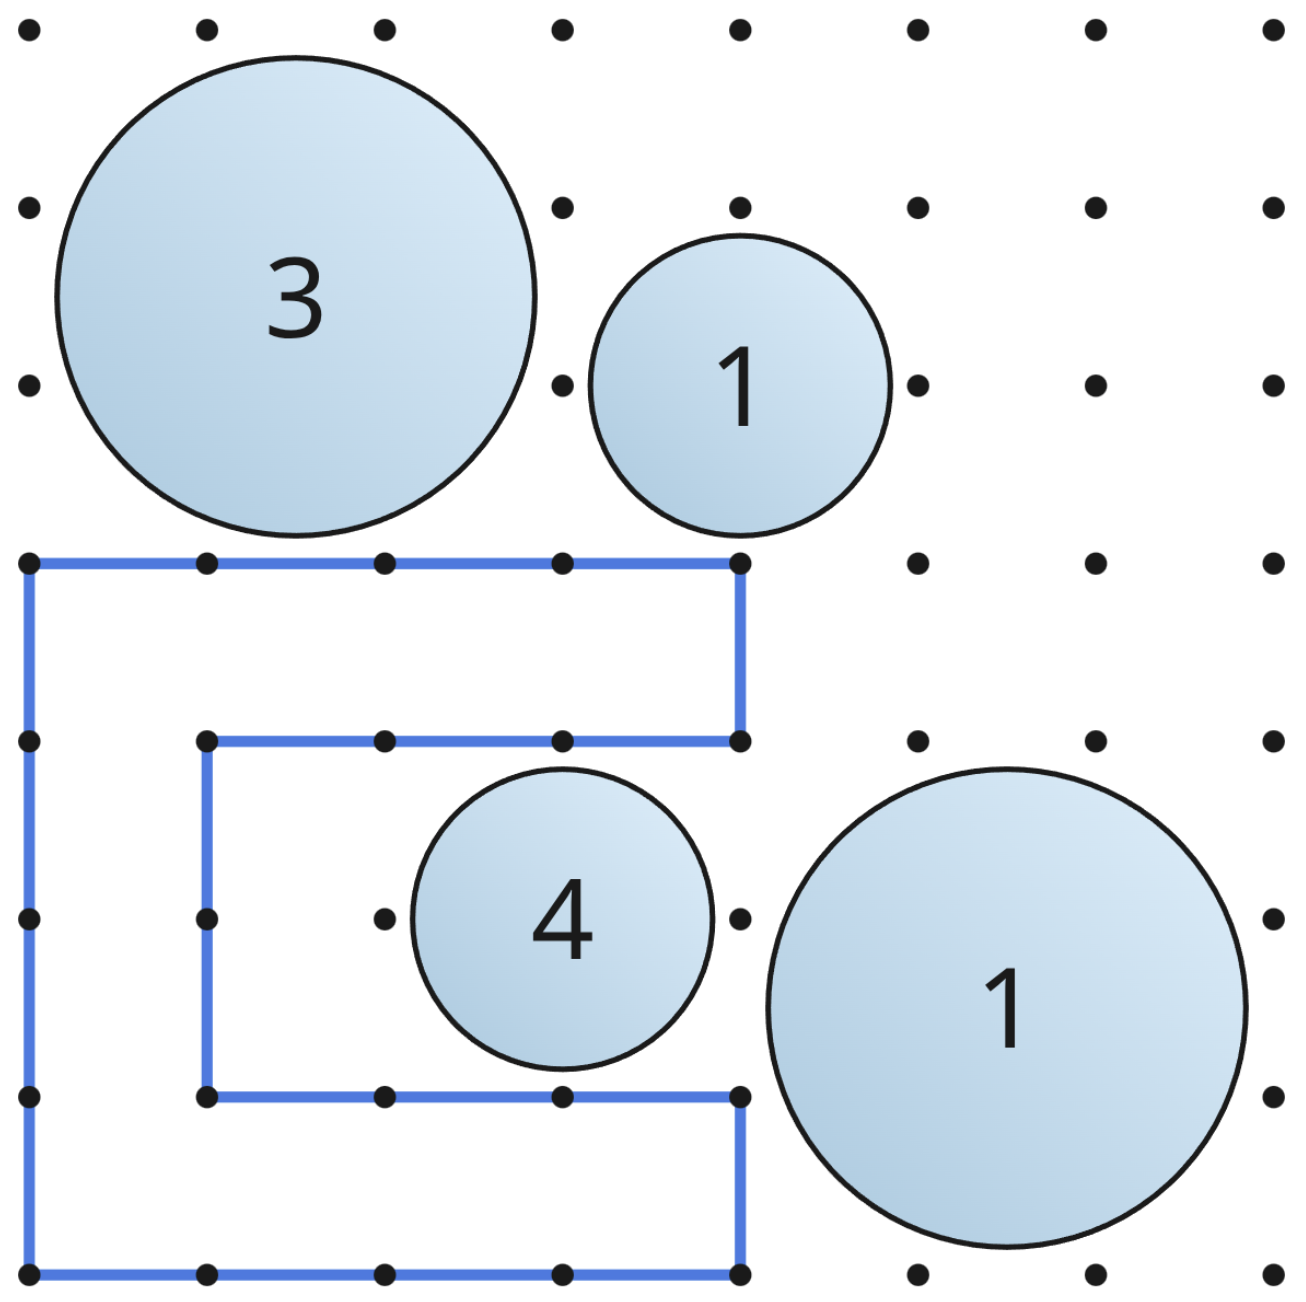
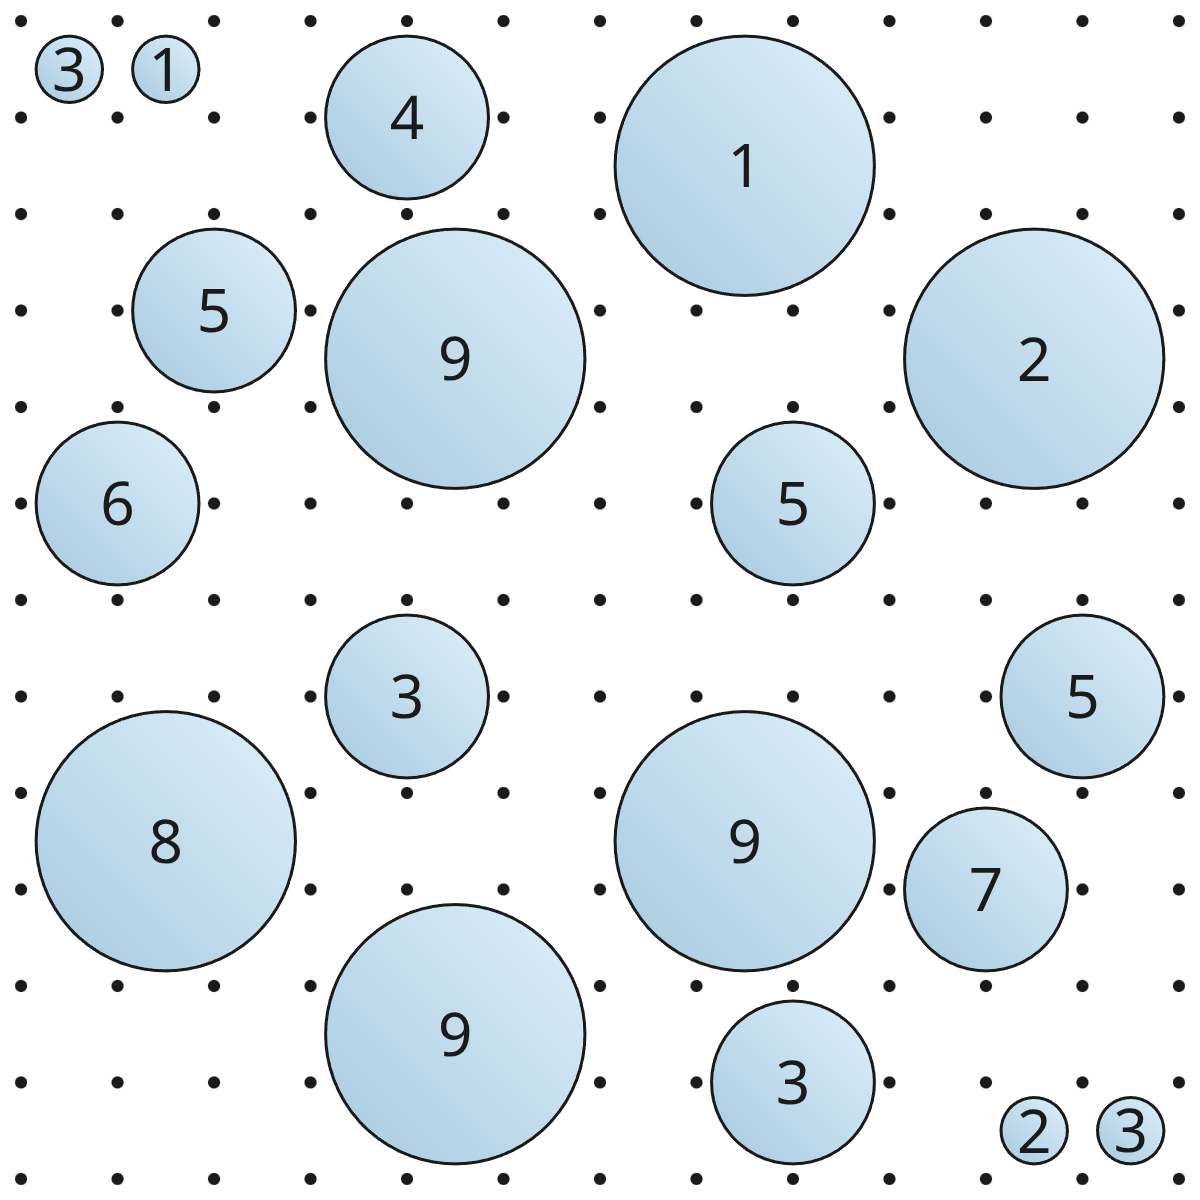
In Super Slitherlink, your goal is to draw a single closed loop by connecting neighboring dots with horizontal and vertical segments. The loop may not cross or touch itself.
Each clue covers a rectangular area of the grid and hides the dots inside it, so the loop can't pass through them. The number tells you how many segments along that rectangle's border are part of the loop.
Here is a solved example with four clues:
Can you solve this puzzle? Its clues are the first 18 digits of π.
Each of the nine clues below covers a 2×3 rectangle, so it counts how many of the ten segments along its border belong to the loop. Every clue starts out as an 8, drawn like the digits on a digital clock. Choose a digit from 0 to 9 for each clue by erasing lines from its 8, so that the resulting Super Slitherlink puzzle has exactly one solution.
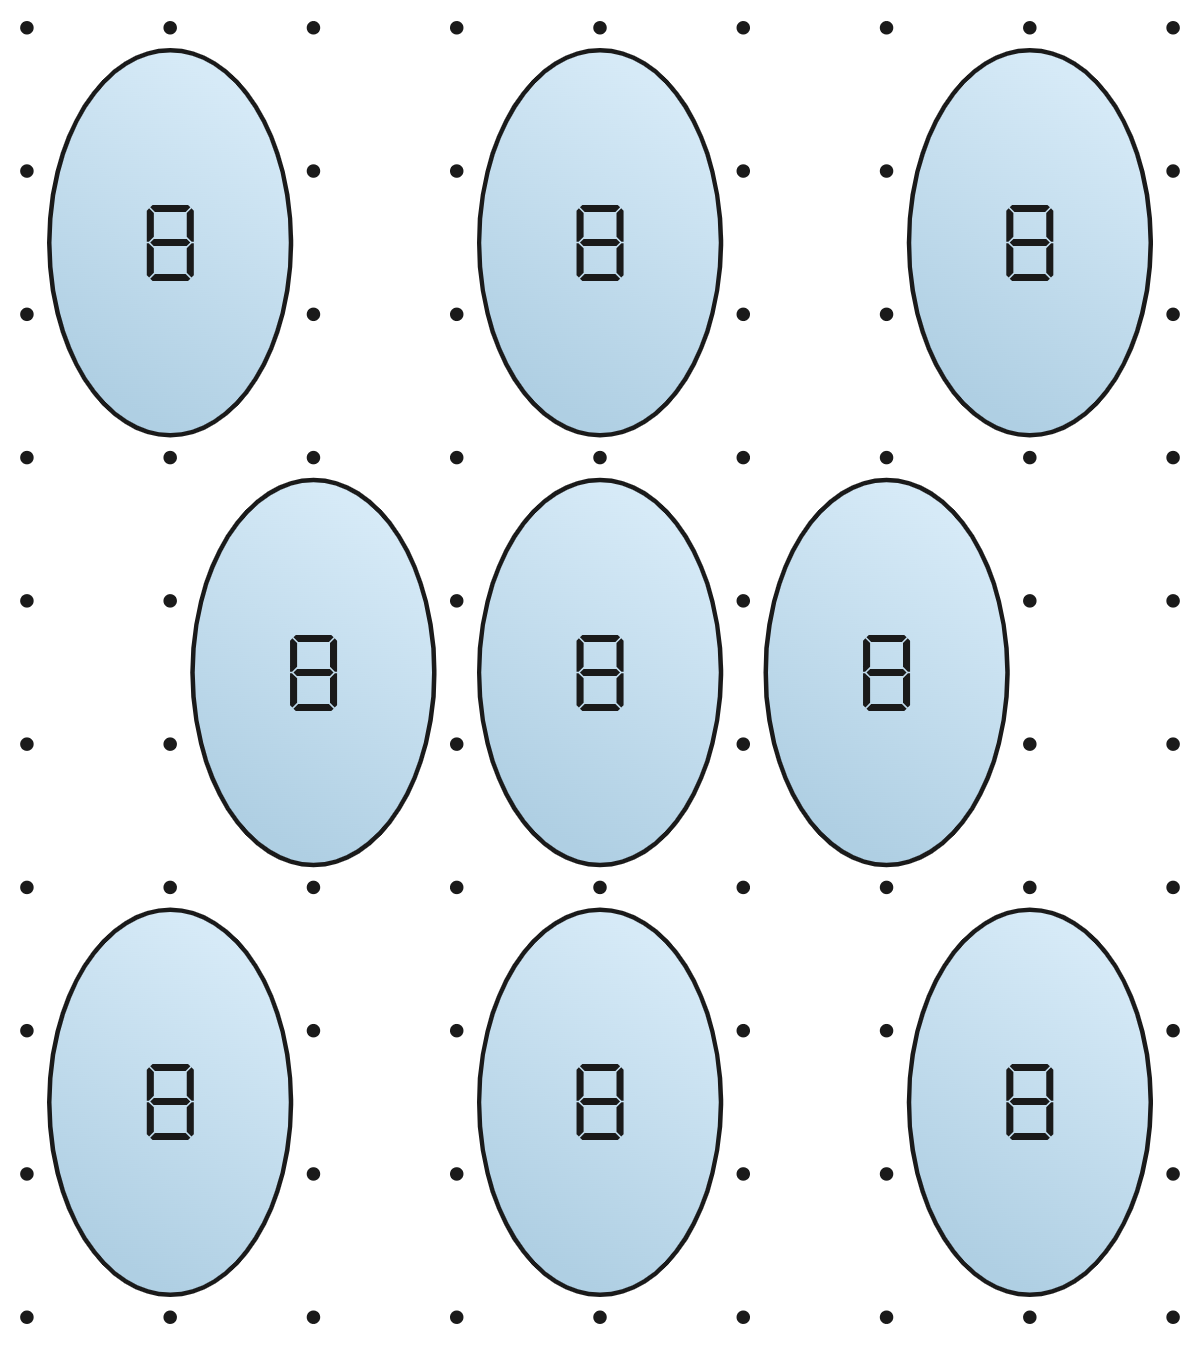
There are many ways to do this, but only one of them spells a nine-letter English word when you turn the puzzle upside down and read the clues as letters, calculator-style (an upside-down 3 reads as E, a 7 as L, and so on), left to right and top to bottom.
What is that word?
This puzzle combines Slitherlink with a Latin square. Every clue covers a single cell and tells you how many sides of that cell are part of the loop. The sixteen clues are digits from 0 to 3, and every row and every column of clues contains each digit exactly once, but only one clue is shown.
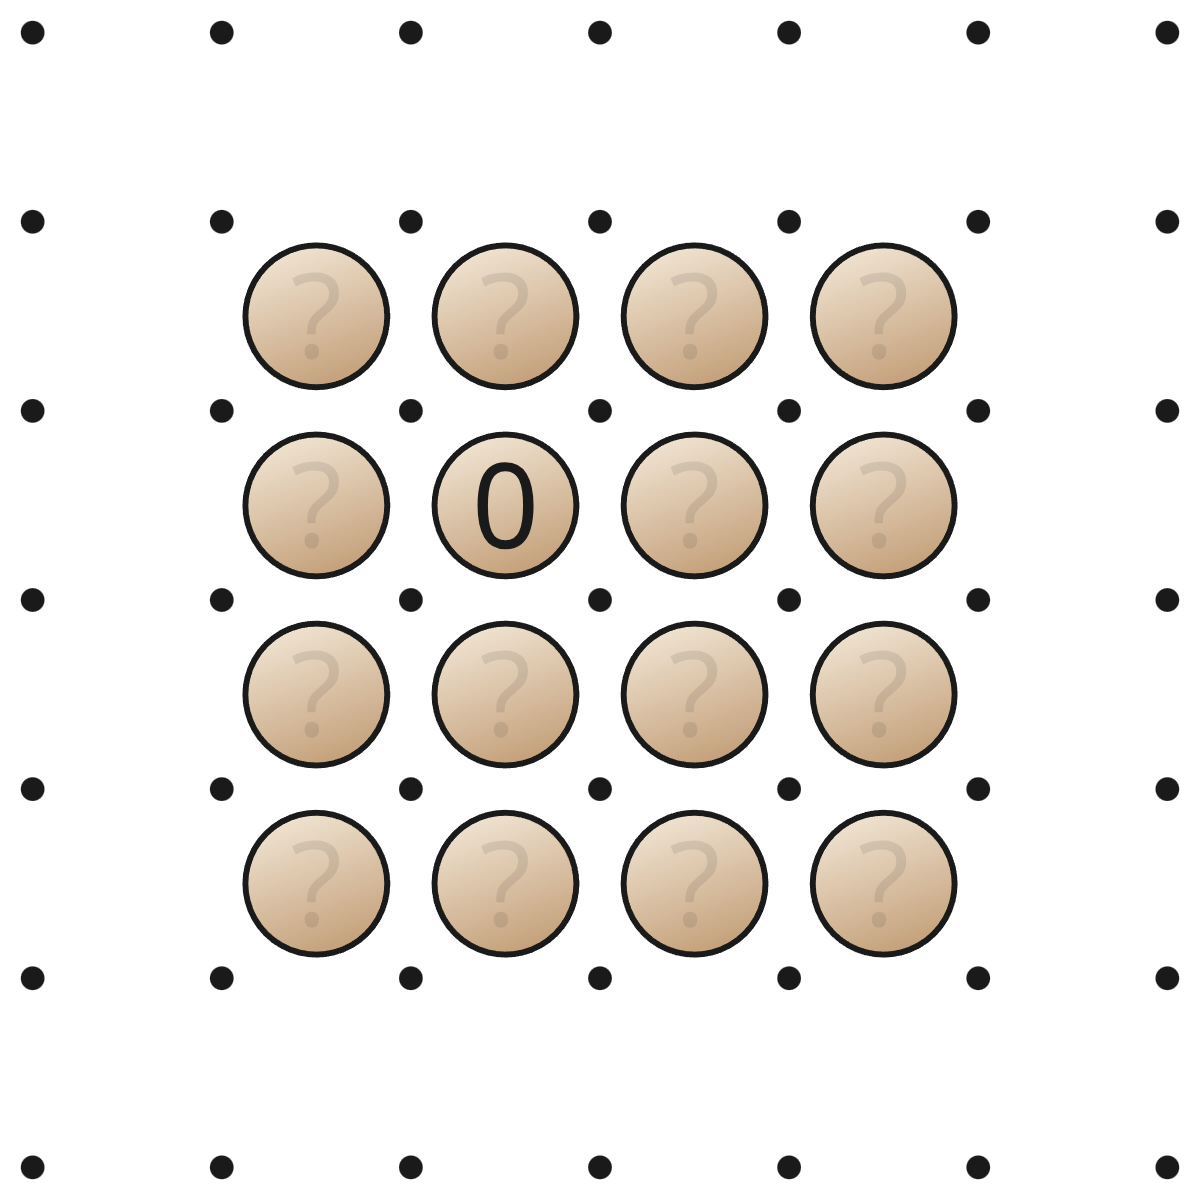
Can you find the digits and the loop?
Have an answer you feel proud of? When you apply, include a line at the bottom of your resume saying "Answer to 3b1b talent page Slitherlink puzzle" with a link to a short write-up of your solution.
Featured work
Cutting inference cost by up to 20x
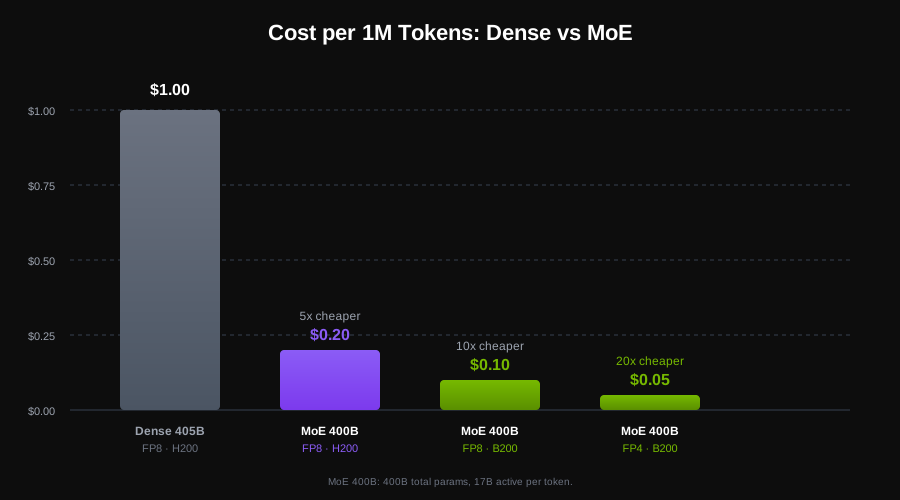
We paired Mixture-of-Experts models with Blackwell-specific optimizations: NVFP4 quantization, speculative decoding, and memory management in TensorRT-LLM. A 405B dense model on H200 costs $1.00 per million tokens; a 400B MoE model on B200 in NVFP4 costs $0.05.
 Read the post
Benchmarking NVIDIA's Vera CPU for agents
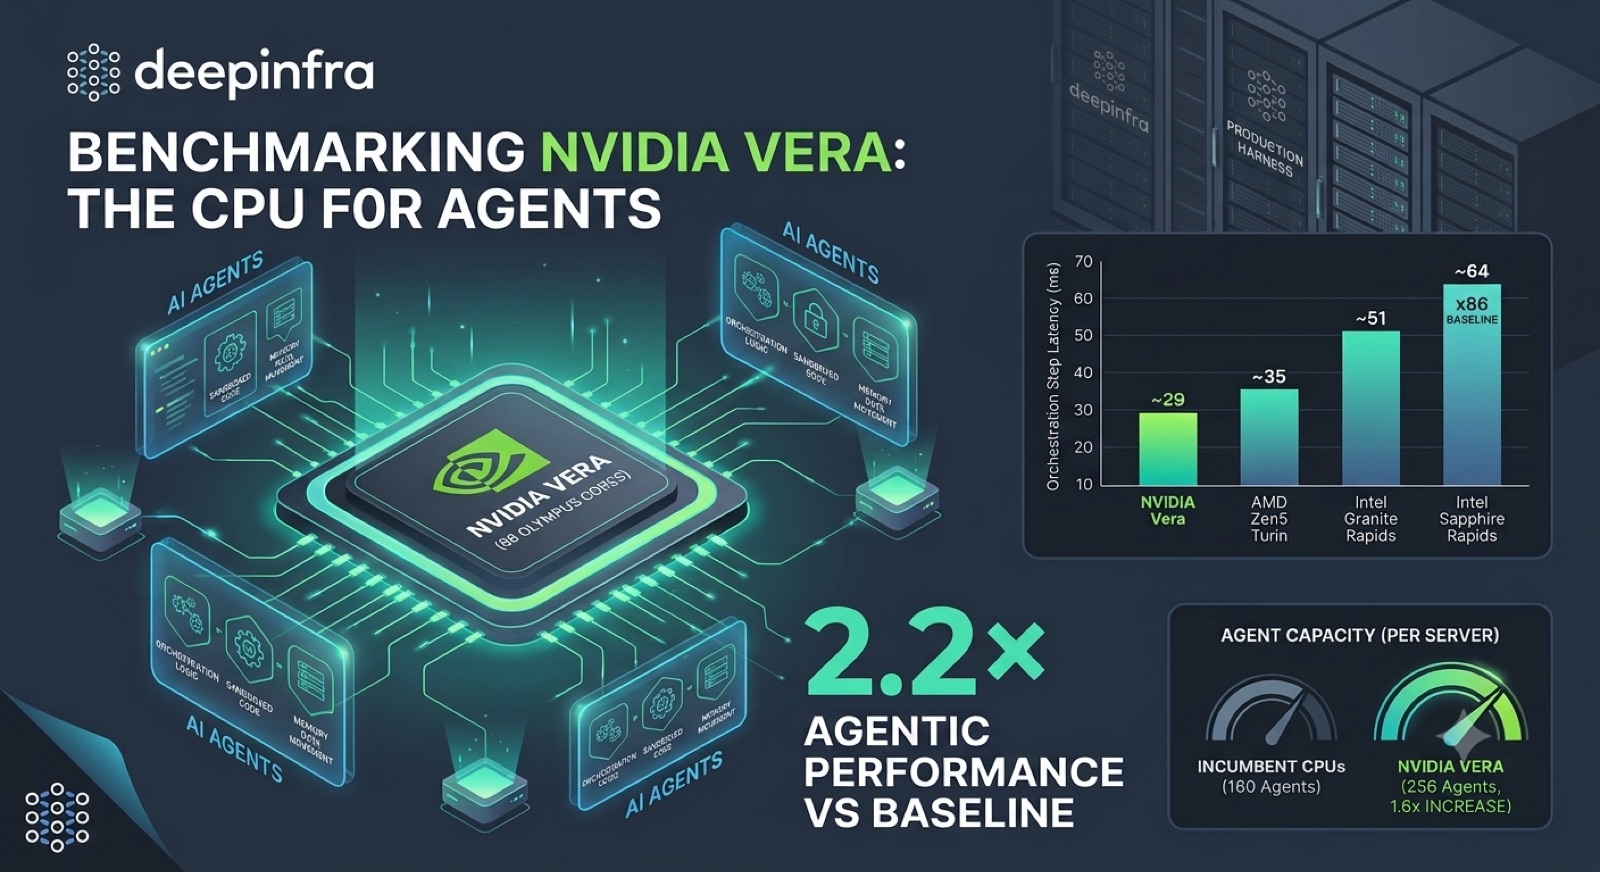
We benchmarked NVIDIA's Vera CPU against x86 chips on agentic workloads. Vera ran orchestration steps 2.2x faster than Sapphire Rapids and held 1.33–1.6x more sandboxed agents per core under a strict latency SLO. We also measured what microVM isolation actually costs.
 Read the post
Serving frontier models on NVIDIA's inference stack
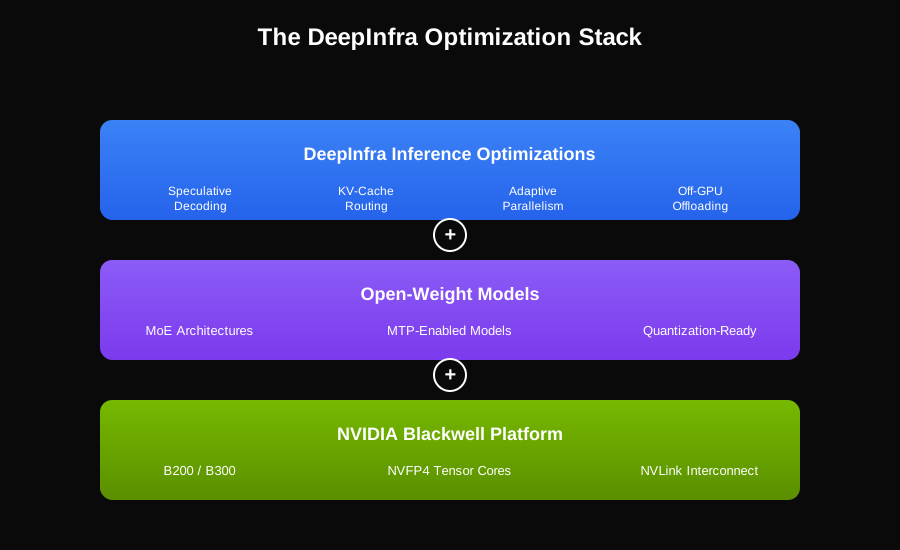
We serve frontier open models on B300 GPUs using TensorRT-LLM, NVIDIA Dynamo for distributed serving, and NVFP4 quantization. With this setup, one B300 does the work of four H200s on DeepSeek V4.
 Read the post

What our team says
I've found the rare place that passes Charlie Munger's career test: I believe in what we build at DeepInfra, I admire the people leading it, and I enjoy working with this team.
— Pernekhan Utemuratov
Working at a fast-moving startup like DeepInfra means wearing many hats and learning something new every day, and I love that challenge. Being surrounded by smart, inspiring people makes it fun, too.
— Boyka Nacheva